MARB research update · September 17, 2026 · Five exports
Astra vs Grok Bot: M3-CRETE assembly results
Astra placed its matched components closer to the reference. Grok Bot matched more of the reference assembly. Neither produced a verified, build-ready machine.
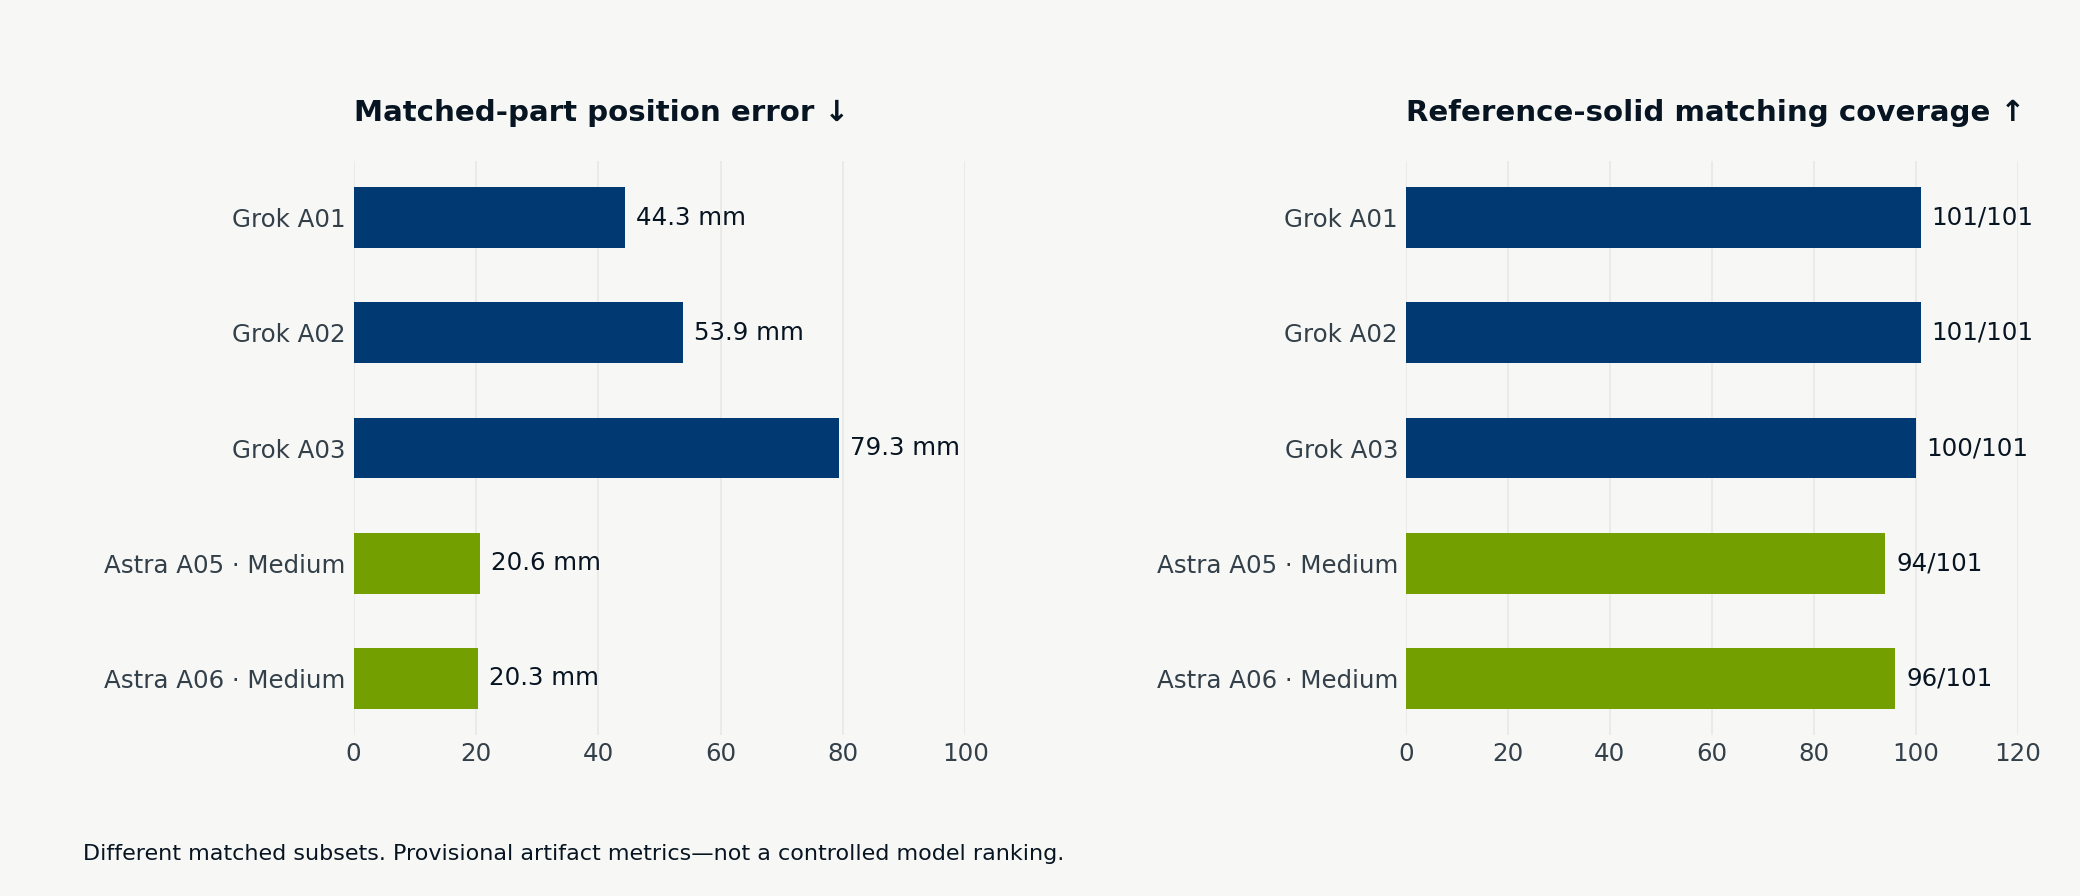
Astra's two Medium-effort runs recorded relative-position median errors of 20.6 and 20.3 mm. Grok Bot's three exports recorded 44.3, 53.9 and 79.3 mm. Astra's lower errors apply to smaller matched sets: 94 and 96 reference solids, compared with Grok's 101, 101 and 100.
The assembly task
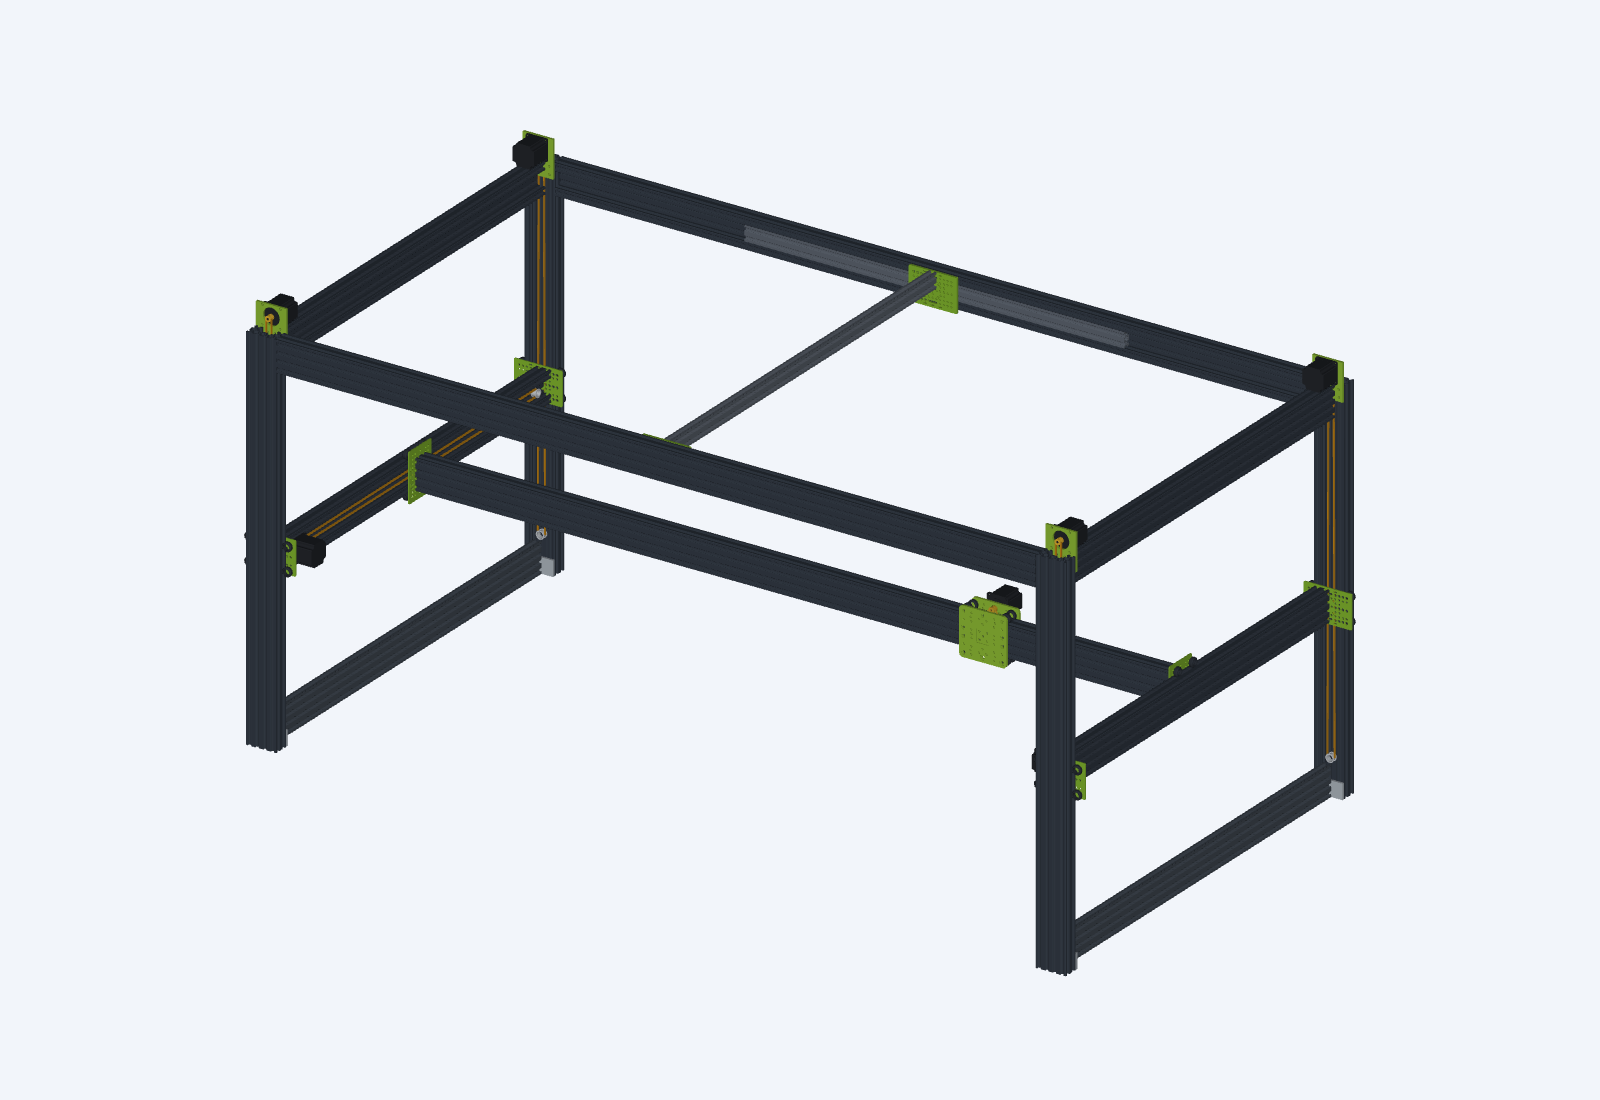
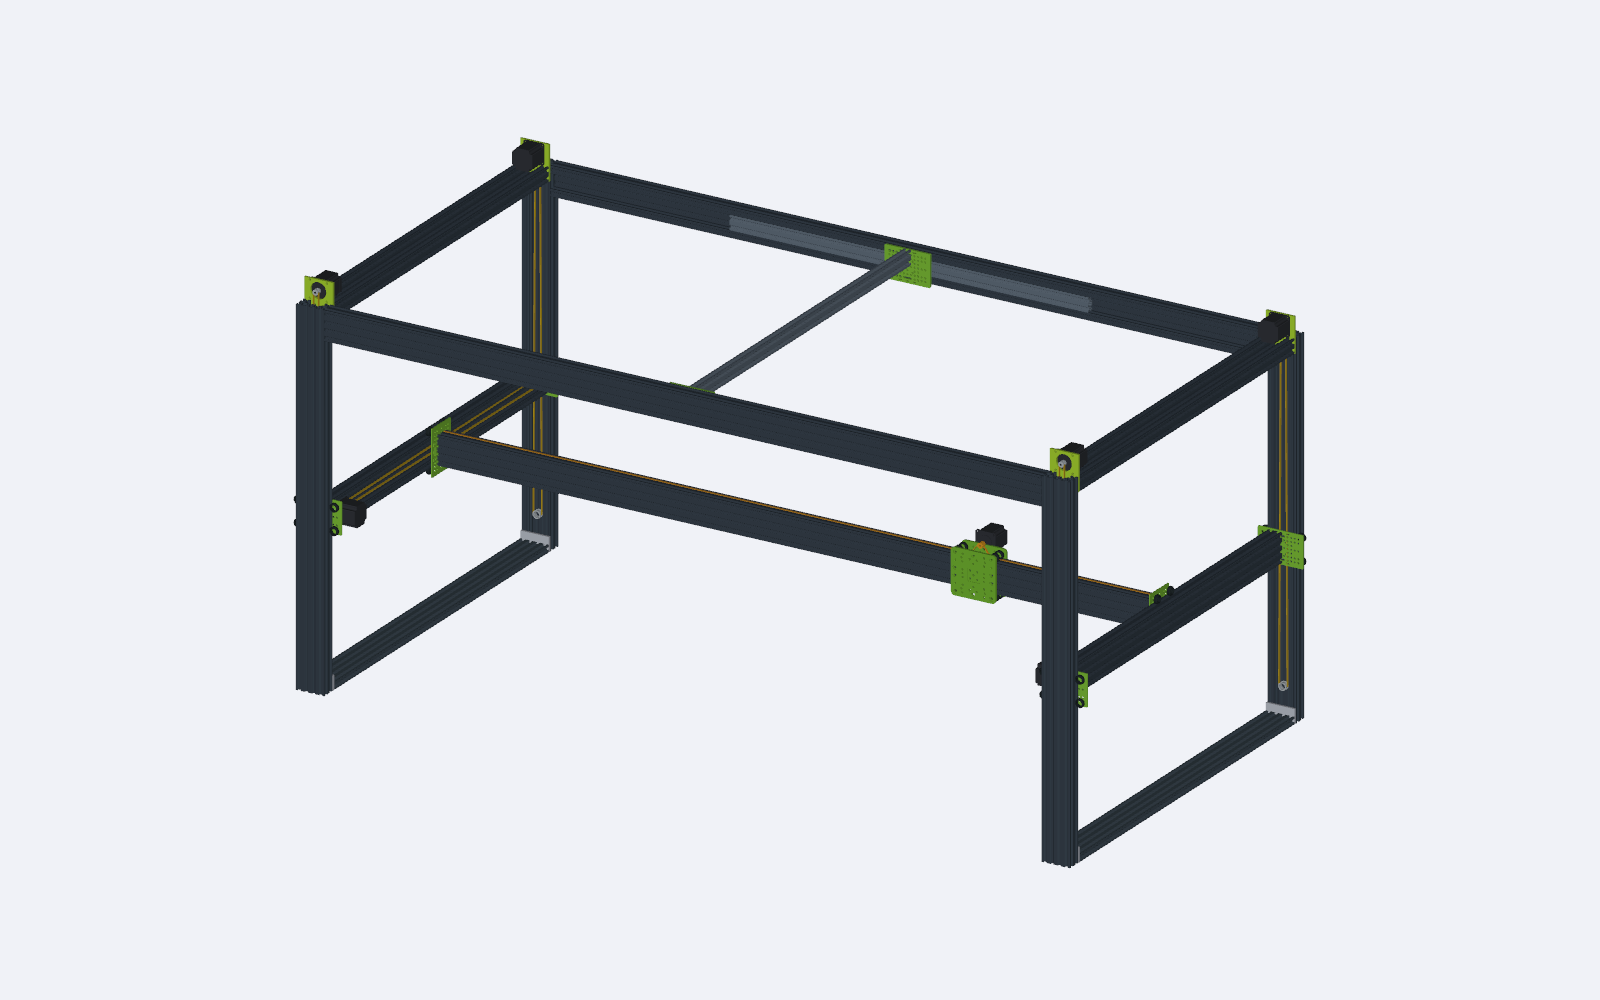
The M3-CRETE M3-2 task asks an agent to assemble a roughly two-metre gantry from 14 authored STEP components and four reference images. The target has about 100 placed instances, represented by 101 reference solids. Required returns include an assembly STEP, editable source, review images and a run log. The printhead payload and final tool interface are out of scope.
Grok A01
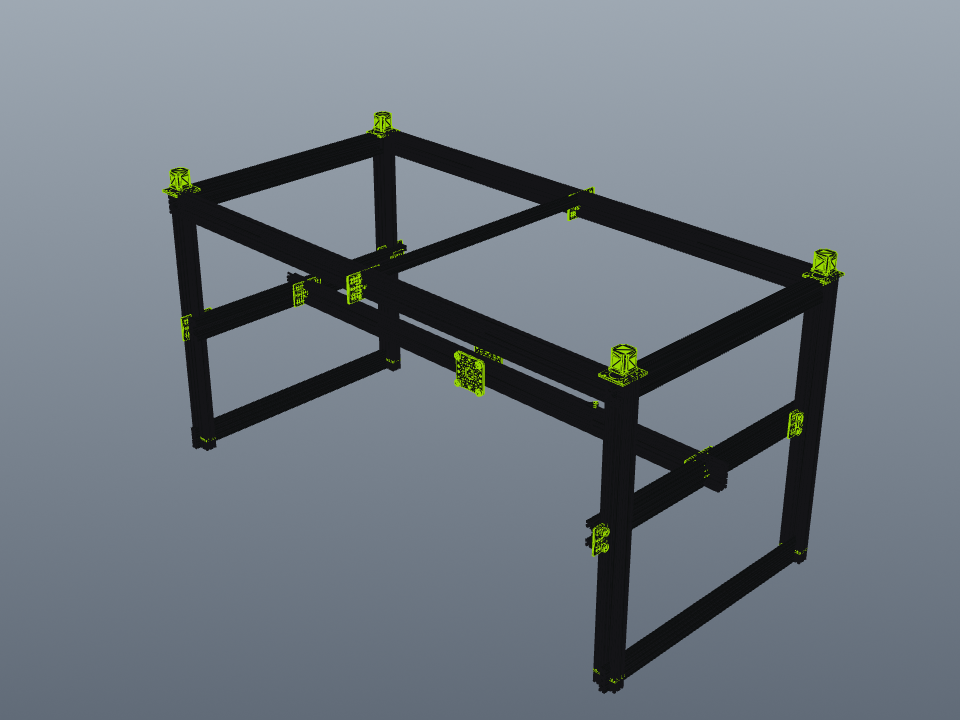
Grok A02
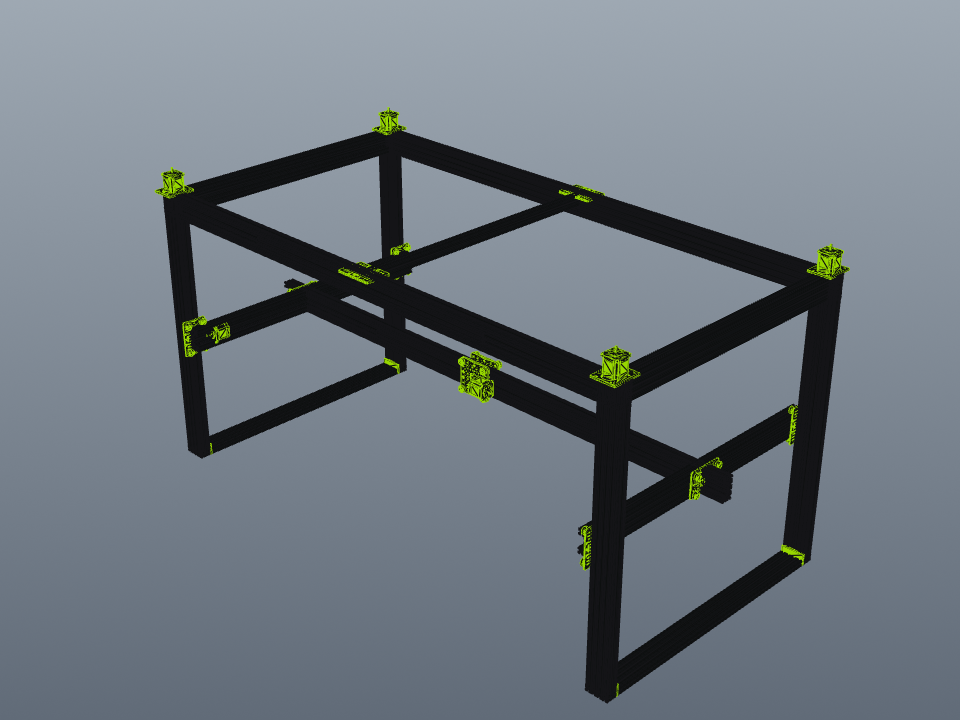
Grok A03
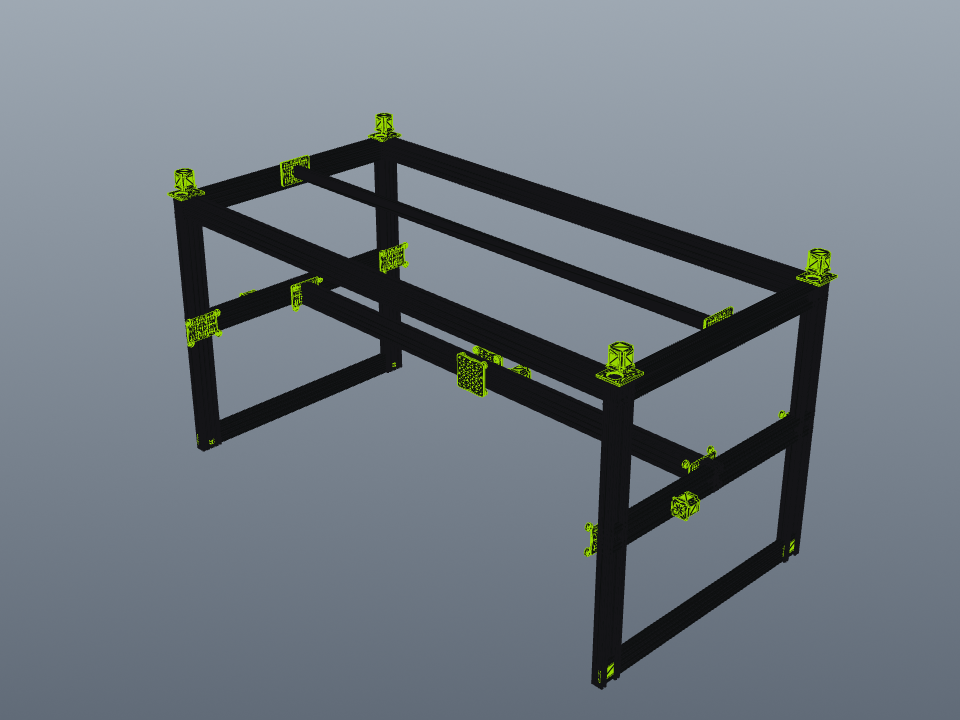
Astra A05 · Medium
Astra A06 · Medium
Results
All five exported STEP files were measured against the same reference with frozen scoring code. The review did not execute the submitted scripts. These are Sunnyday Technologies' measurements, not third-party testing.
| Artifact metric | Grok A01 | Grok A02 | Grok A03 | Astra A05 · Medium | Astra A06 · Medium |
|---|---|---|---|---|---|
| Reference solids matched / 101 | 101 | 101 | 100 | 94 | 96 |
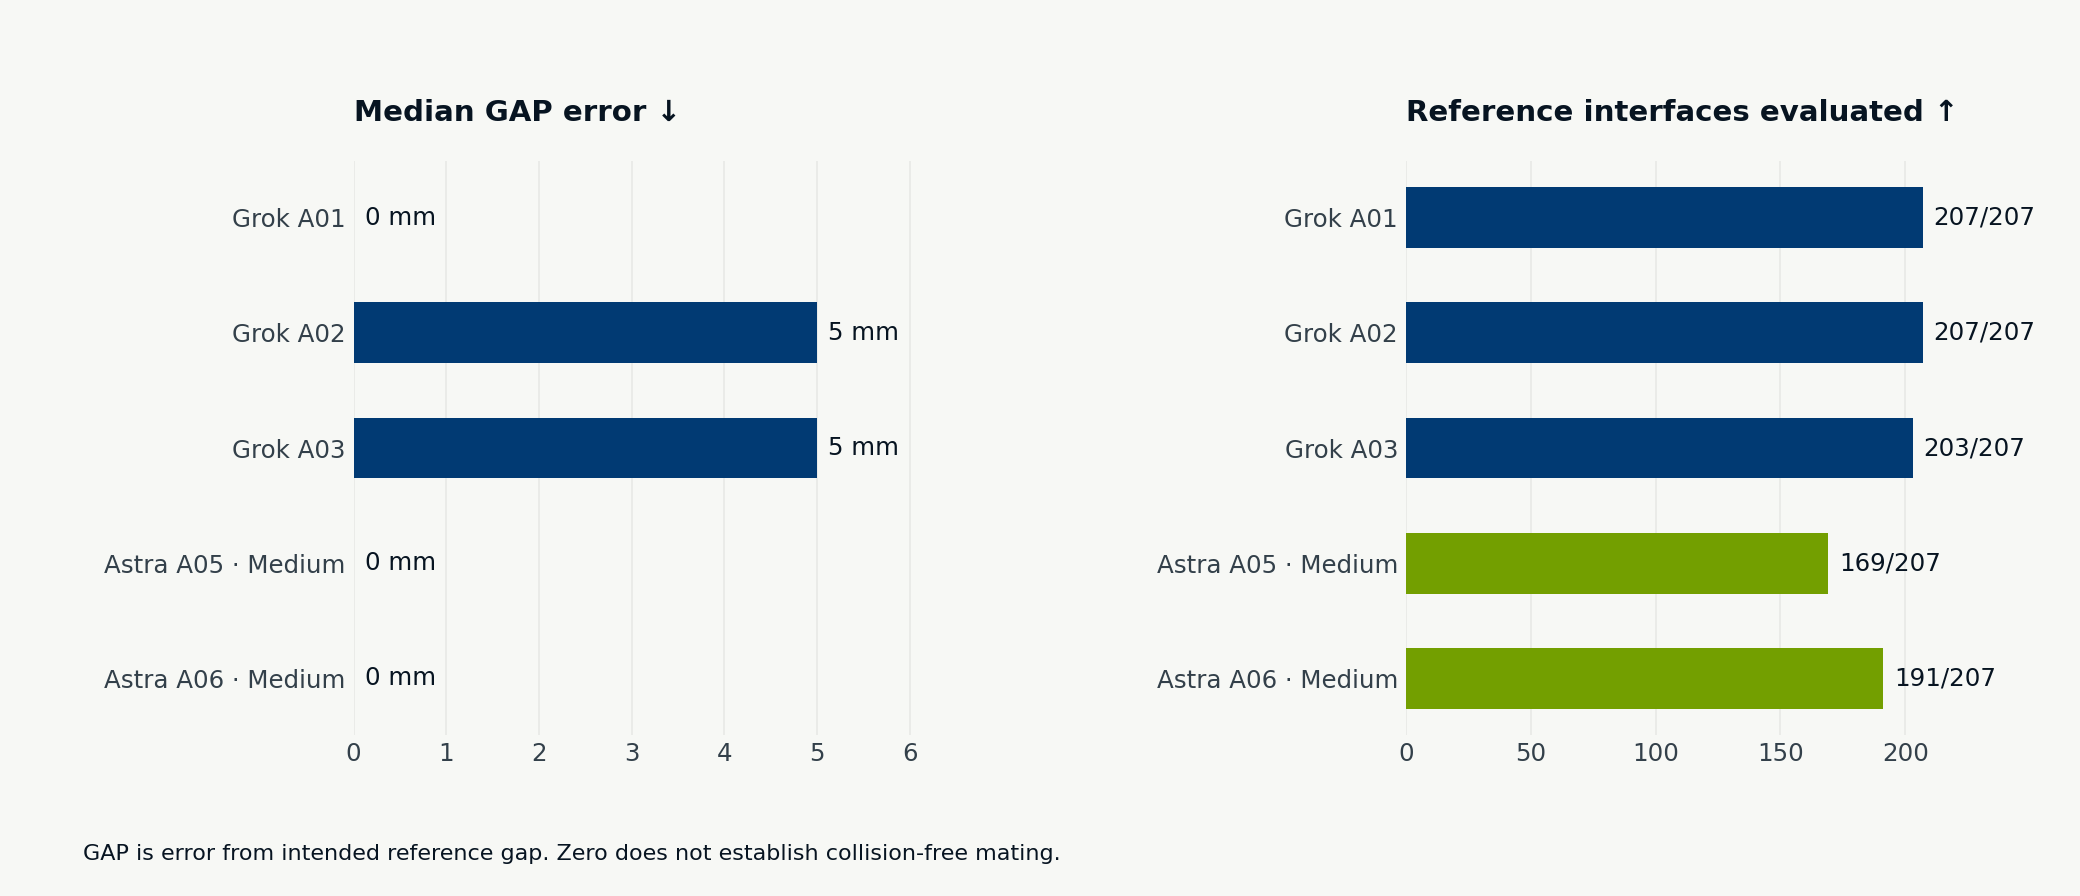
| Interfaces evaluated / 207 | 207 | 207 | 203 | 169 | 191 |
| Relative POS median error ↓ | 44.3 mm | 53.9 mm | 79.3 mm | 20.6 mm | 20.3 mm |
| Absolute POS median error ↓ | 84.2 mm | 94.7 mm | 88.5 mm | 70.9 mm | 64.3 mm |
| GAP median error ↓ | 0.0 mm | 5.0 mm | 5.0 mm | 0.0 mm | 0.0 mm |
| Evaluated GAP errors ≤1 mm ↑ | 55.1% | 39.1% | 42.4% | 72.8% | 75.9% |
| ORIENT aligned, asymmetric solids ↑ | 60.8% (31/51) | 72.5% (37/51) | 46.0% (23/50) | 65.9% (29/44) | 67.4% (31/46) |
Assembly outcomes
Astra: A06 matched two more reference solids and evaluated 22 more interfaces than A05, with a similar position median. Both exports include additional drive components and assumptions about extrusion lengths. Their agents reported unresolved fits, overlaps and mounting details. A05 leaves seven reference solids unmatched; A06 leaves five.
Grok: A02 improved orientation alignment over A01 but increased position and GAP errors. A03 lost ground on relative placement and orientation. Its absolute-position error improved over A02, while its GAP median stayed at 5.0 mm. The slightly higher share of GAP errors within 1 mm covers fewer interfaces and does not establish an overall improvement.
A03's source replaces the supplied 1,000 mm spreader with a generated 1,920 mm rectangular bar, not the authored V-slot profile. We have not established whether that substitution explains its unmatched solid. Wheel seating, belt routing and plate orientation remain approximate in the agent's account.
Test conditions and evidence
| Runs | Driver / effort | Reported CAD runtime | Key limitation |
|---|---|---|---|
| Grok A01–A03 | Grok Bot; underlying model and effort unavailable | CadQuery 2.8.0 / Python 3.13.5 | Incomplete execution evidence; A02 reports delegation; A03 has inconsistent metadata |
| Astra A05 | GPT-6 Astra / Medium | CadQuery 2.7.0 / Python 3.11.15 | Diagnostic/non-blind |
| Astra A06 | GPT-6 Astra / Medium | CadQuery 2.6.1 / Python 3.11.9 | Diagnostic/non-blind |
Astra's configured Medium effort is supported by local session records, not independent server-side verification. It received historical benchmark context. A06 also received an automated shell suggestion, but no placement guidance.
Grok received blind-kit instructions; isolation was not independently audited. A01's supplied conversation excerpts support CadQuery execution but are not authenticated host transcripts. A02's original assembly and rendering command records remain unavailable. Its reported executor delegation conflicts with the single-agent instructions.
A03's run log identifies the new attempt, but other fields retain earlier attempt labels. Its input-kit hash has not been linked to the retained handoff, and no shell transcript is included. Its return manifest verifies successfully. These limitations remain part of the result; original records were not rewritten.
CadQuery, Open CASCADE and setup
Grok Bot's returned scripts import, place and export parts with CadQuery. CadQuery uses Open CASCADE through OCP bindings: an Open CASCADE STEP header does not indicate a separate CAD workflow. CADCLAW was reported as the review-rendering tool, not the assembly exporter.
Grok reports creating its own Python environment and installing dependencies during each attempt. The successful Astra runs used a separate automated preparation phase. Both products used a runtime; the distinction is how setup was handled. This evidence does not establish a public Grok tool API or a newly introduced capability.
| Run | Preparation | Assembly benchmark | Reported total |
|---|---|---|---|
| Grok A01 | Included; not separated | Not separated | 6.63 min |
| Grok A02 | Included; not separated | Not separated | 11.40 min |
| Grok A03 | Included; not separated | Not separated | 7.57 min |
| Astra A05 | 5m 40s | 19m 55s | 25m 36s |
| Astra A06 | 7m 52s | 13m 36s | 21m 29s |
Four earlier Astra attempts stopped during setup and produced no scored geometry. Totals include packaging; timing boundaries and rounding differ. Comparable token counts are unavailable. These records do not support a normalized speed or cost-efficiency ranking.
Comparison with earlier MARB results
The three zero GAP medians equal the leading numerical value on the June board. Astra's roughly 20 mm position medians are below that board's 30.4 mm Fable ultra result. These are numerical comparisons only: historical conditions differ, matching coverage varies, and the new exports do not form qualified repeat-run cohorts. The official leaderboard is unchanged.
Method and limits
Grading used a frozen CADCLAW source revision, CadQuery 2.7.0 and OCP 7.8.1.1.post1. A reference-against-itself control returned zero position and GAP errors and full orientation alignment. It checks the scoring setup, not equivalence with every historical environment.
- POS measures placement disagreement among matched solids; a median is not a maximum error or fabrication tolerance.
- GAP measures error from the intended reference bounding-box gap. Touching or overlapping boxes have zero distance.
- ORIENT uses bounding-box axes, excludes symmetric shapes and does not fully test functional mating.
Independent interference, floating-part and buildability checks were not rerun for this comparison. No physical validation is claimed. A reliable model comparison needs repeated runs with fixed model, effort, runtime, kit, prompt and scorer, reporting failures and variation alongside the best result.